Ori-Finder prokaryotic suite identification of replication origins in prokaryotic genomes
- What is the replication origin?
- The major features of replication origin in Archaea
- Ori-Finder 2, identification replication origins in archaea
- What are the origin recognition boxes (ORB)?
- What are the four disparity curves?
- MEME, a tool for motif discovery and searching.
- FIMO, scanning for occurrences of a given motif.
- REPuter, fast computation of maximal repeats in complete genomes.
- Performance evaluation.
1. What is the replication origin?
- The replication origin (also called the origin of replication) is a specific sequence in the genome where DNA replication is initiated. This can either involve the replication of DNA in living organisms such as prokaryotes and eukaryotes, or that of DNA or RNA in viruses, such as double-stranded RNA viruses.
- DNA replication may proceed from this point bidirectionally or unidirectionally. The specific structure of the origin of replication varies somewhat from species to species, but all share some common characteristics such as high AT content. The origin of replication binds the pre-replication complex, a protein complex that recognizes, unwinds, and begins to copy DNA. [From Wikipedia]
2. The major features of replication origin in Archaea
-
Archaea is classified as a separate domain in the three-domain system and shares some similar features
with both bacteria and eukaryotes. Similar to the mechanism in bacteria, the oriCs are the
intergenic regions adjacent to the replication proteins, such as Cdc6 protein, origin recognition
complex protein, whip and DNA primase, and contain the origin recognition boxes (ORB) which are AT-rich
unwinding element and several conserved repeats. In some organisms, G-stretches are found at the end of
ORBs. As well some archaea adopt multiple oriCs to initiate DNA replication like the mechanism
in eukaryote.
3. Ori-Finder 2, identification replication origins in archaea
-
The online tool Ori-Finder 2 utilizes an integrated method to automatically predict the replication
origins in archaeal genome including disparity analysis using the Z-curve method, the distribution
of ORB with FIMO tool, and the
occurrence of genes frequently close to replication origin. The web server also could analyze the
un-annotated complete genome with two embedded gene-finding programs,
Zcurve and
Glimmer, for gene identification.
Users could submit an annotated or unannotated genome sequence to the web server. For annotated genome, we recommend that users submit sequence file in GenBank format or upload sequence file in FASTA format as well as its corresponding protein table (PTT) file. The web server could also analyze the unannotated genomes by integrating two gene-finding programs, ZCURVE and Glimmer, for gene identification and BLAST program for functional annotations of genes. Then all the intergenic sequences are scanned by FIMO to obtain the ORB sequences and by REPuter program to identify repeats. Finally, all the intergenic sequences adjacent to the replication genes with ORB sequences are predicted as oriCs. Since the approach relies on prior knowledge of oriCs in archaea, it will fail to identify oriCs adjacent to genes of unknown function, but which might be involved in DNA replication. In order to overcome the drawback, the intergenic sequences, which contain more than three conserved motifs, will be also predicted as oriCs. BLAST searches are also performed against DoriC, a database of bacterial and archaeal replication origins, to search the homologs. The conserved motifs of ORB sequences used in FIMO were obtained from the DoriC database. All the records in DoriC database were organized into several clusters by the taxonomy. And the conserved ORB motifs were calculated from the corresponding cluster by MEME program. Each run of Ori-Finder 2 is assigned a job ID and takes several minutes to predict oriCs in the whole process. Users could retrieve their job with the job ID or be notified by email if an email address on the submission page is specified.
In fact, during the prediction of Ori-Finder 2, when users select the motif of Halobacteriaceae, Methanobacteriaceae, Methanomicrobia, and Methanococcaceae, the intergenic sequences, which are not adjacent to replication–related genes and within more than two motifs, will b e predicted as oriCs. For the motif of Sulfolobacea and Thermococcaceae, the intergenic sequences, which are not adjacent to replication–related genes and within all three species of motifs, will be predicted as oriCs. This method can strike a balance between accuracy and sensitivity.
In the output webpage, the information of the genome including size, GC level, location of replication genes and location of oriCs is displayed as an HTML table. In addition, detailed information of repeats in oriCs identified by REPuter program, motifs recognized by FIMO and homologous oriCs in DoriC database are also presented. The ORB sequences are also displayed in the corresponding oriC table including matched sequence, location, strand, score and P-value. Finally, a PNG figure embedded in the output webpage are generated to display RY, MK, GC or AT disparity curves, replication proteins, and oriCs.
Finally, we recommend that users select the 'common' motif to search the oriCs at the first prediction. Because the common motif is the most conserved and frequent sequence in all the archaeal oriCs. Then users could select the special motif based the taxonomy of archaea to perform Ori-Finder 2. Through analysis of the two results, users could find the appropriate oriCs.
4. What are the origin recognition boxes (ORB)?
-
Origin recognition box (conserved DNA sequence) is found to be integrated in multiple copies at
oriCs. The sequences often play as an enhancer for oriC, and a G-rich inverted repeat
always locates in at the end of ORB.
The ORB motifs used in Ori-Finder 2 are obtained from DoriC database. All the records in DoriC database are classified to several clusters by organism taxonomy, such as, Methanobacteriaceae, Methanomicrobia, Methanococcaceae, Sulfolobaceae and Thermococcaceae. The conserved motifs are calculated from corresponding cluster by MEME program. In addition, the most common motif is calculated from all the records in DoriC database.
Here, FIMO uses the position specific probability matrix (PSPM) to search these motifs in oriCs. And the motifs presented in the webpage are generated by WebLogo. Users could download PSPM file here.
5. What are the four disparity curves?
-
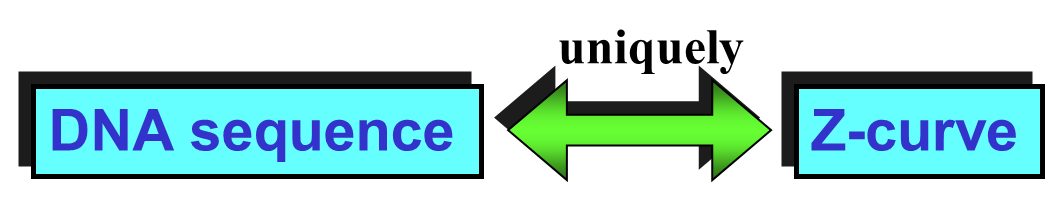
The Z curve is a unique three-dimensional curve representation for a given DNA sequence in the sense
that each can be uniquely reconstructed given the other
[Zhang and Zhang 1994].
-
The Z curve is composed of a series of nodes P0, P1,
P2, ..., PN, whose coordinates xn,
yn and zn (n=0,1,2,...,N, where N is the length of the DNA
sequence being studied) are uniquely determined by the so-called Z-Transform of DNA sequence,
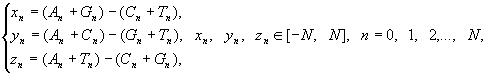
where An , Cn, Gn and Tn are the cumulative occurrence numbers of A, C, G and T, respectively, in the subsequence from the 1st base to the n-th base in the sequence. We define A0=C0=G0=T0=0.
The Z curve is defined as the connection of the nodes P0, P1, P2, ..., PN one by one sequentially with straight lines. Note that we define x0=y0=z0=0 such that the Z curve always starts from the origin of the three-dimensional coordinate system. - The three components all have biological meanings.
The x-component of a Z curve displays the distribution of purine/pyrimidine (R/Y) bases along the sequence;
The y-component of a Z curve displays the distribution of amino/keto (M/K) bases along the sequence;
The z-component of a Z curve displays the distribution of strong-H bond/weak-H bond (S/W) bases along the sequence.
- The xn and yn components are termed RY disparity and MK disparity curves, respectively. Similarly, the AT and GC disparity curves are defined by (xn + yn)/2 and (xn - yn)/2, which shows the excess of A over T and G over C, respectively, along the genome. The RY and MK disparity curves, as well as AT and GC disparity curves can be used to predict oriCs of various genomes.
- Your could learn more about information and applications via visiting Z curve database.
6. MEME, a tool for motif discovery and searching.
-
MEME is a tool used to discover motifs in a group of related DNA or protein sequences
[Bailey, Boden et al. 2009]. In Ori-Finder 2,
the ORB motifs are identified by MEME program. We classified the records of DoriC database to several
clusters by taxonomy, and used MEME program to search the conserved motifs.
Command:
meme <File> -dna -mod anr -maxw 20 -minw 10 -revcomp -maxsize 200000 -oc all -nmotifs 3You could visit http://meme.nbcr.net/meme/doc/meme.html to get more information.
7. FIMO, scanning for occurrences of a given motif.
-
FIMO is a tool for searching biological sequence databases for sequences that contain one or more known
motifs [Grant, Bailey et al. 2011].
In Ori-Finder 2, we use the FIMO to search the ORB motifs in candidate oriCs.
You could visit http://meme.nbcr.net/meme/fimo-intro.html to get more information.
8. REPuter, fast computation of maximal repeats in complete genomes
-
REPuter is a classic tool to compute exact repeats and palindromes in entire genomes efficiently
[Kurtz, Choudhuri et al. 2001].
In Ori-Finder 2, we use it to search repeats in all the oriCs.
Command:
repfind -f -l 8 -best 50 -h 3 -sYou could visit http://bibiserv.techfak.uni-bielefeld.de/reputer/manual.html to get detail information.
9. Performance evaluation.
In order to evaluate performance of Ori-Finder 2, we predicted the oriCs of 13 annotated
chromosomes whose all or part of oriCs have been confirmed by experiment. The following
table presents the result.
The number of positive cases (i.e., the oriCs confirmed by experimental methods) is 19,
and the number of negative cases (i.e., the intergenic sequences excluding these oriCs
confirmed by experimental methods) is 19,219 for annotated genome sequences. Consequently,
the sensitivity, specificity, and precision of Ori-Finder 2 is 63.1%, 99.9%, and 41.3%, respectively.
One reason of the low precision is that we only used the oriCs confirmed by experiments
as positive cases. In fact, some archaea have multiple oriCs, but not all the oriCs
have experimental evidence currently. It is possible that the oriCs with ORB sequences have
the potential of initiating DNA replication. If the oriCs that have been identified
in silico by other groups are also considered as positive cases, the precision will
increase to be 62.1%.
Another reason is that some pair-oriCs we predicted are flanking at one replication gene
and one of them has been confirmed by experiment. In fact, the other oriC also has the
potential of initiating DNA replication.